The Decay of Inbound Data: How Rushed Partners Break Your Digital Workflow During Peak Season
The physical reality of a logistics peak
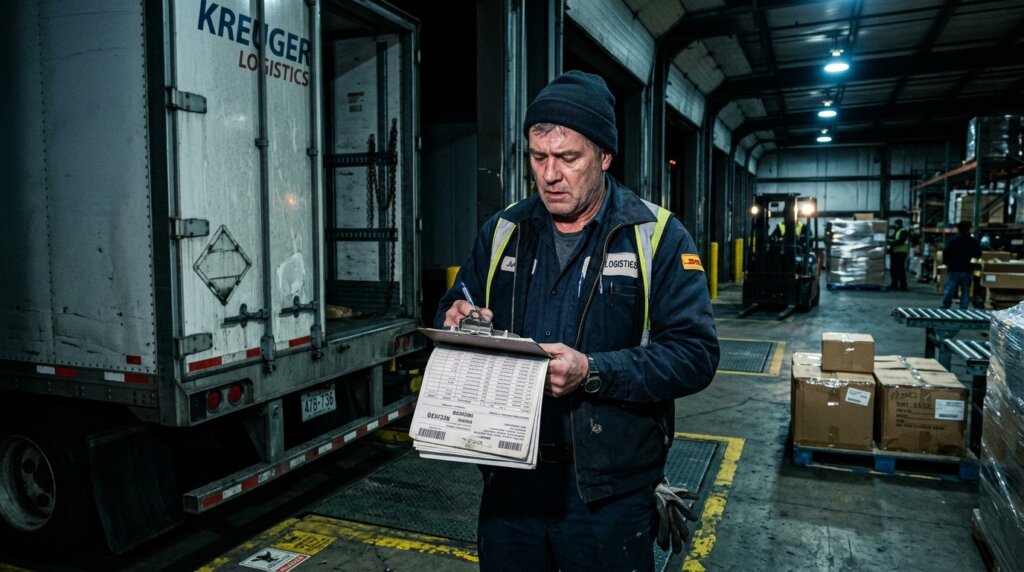
Time pressure within the supply chain during peak season directly dictates the quality of inbound data. In the third and fourth quarters, operations run at maximum capacity. Drivers race against strict driving and resting time regulations. When delivering goods, they often photograph waybills (CMRs) hurriedly in a dark cabin, using a smartphone with a reflective flash. At the loading dock, the priority is clearing the trailer; warehouse workers scribble quick notes with a pen directly over printed barcodes.
These physical actions under time pressure degrade the starting point of administrative processing. To guarantee accuracy, many companies opt for professional data validation for OCR and AI to prevent erroneous input. This specifically impacts parties operating in an open, fragmented market. External supply chain partners, including subcontractors and flexible charters, often lack integration with central enterprise systems. They hand over a tangible document as formal proof of transfer. Companies in a fully closed loop, where their own drivers use internal hardware, generally communicate via a direct API. They generate transfer data digitally. But as soon as the network opens up to external parties, physical paper returns to the loading dock.
The journey from a manually annotated waybill to a stalled system reveals a clear chain reaction. The lifecycle of an unreadable CMR follows a predictable flowchart:
- Source documentation: A document receives handwritten notes on the floor (changes in collies, damage remarks, or a stamp over the address details).
- Digitization under suboptimal conditions: The scribbled document is photographed with poor lighting or scanned crookedly at the terminal.
- Data entry: The scan enters the back office’s digital inbox as an unstructured image file (PDF or JPG).
- Processing attempt: The automated system identifies the document but fails to locate the required data fields.
- Error log: The software rejects processing due to insufficient reliability and routes the file to the manual review queue.
Closed systems versus daily practice
A fully paperless handover by rotating external carriers in the open market is unattainable. Applications work flawlessly when both parties use the same data model. The reality in European road transport, however, relies on chains with multiple logistics service providers. A shipper books a transport with a freight forwarder, who subcontracts it to a carrier, who in turn deploys a foreign charter. This charter does not hold the initial shipper’s API keys. The single universal communication tool across all these links is the paper or digitally scanned CMR. As long as operations depend on physical signatures and handwritten remarks on the tailgate, unstructured data remains the standard input for the receiving party.
Why OCR stumbles over exceptions
Optical Character Recognition (OCR) forms the technical bridge between a physical document and a digital system, but it hits hard limits with unstructured input. Standard algorithms are built on predictability. They demand sharp contrasts between black ink and white paper, and they expect specific data units at predefined coordinates. An invoice number belongs in the top right; a total amount in the bottom right.
The physical reality of a logistics peak creates a mismatch with these technical requirements. Industry observations, such as those detailing discrepancies in pallet registrations, explain how creases in the paper, mud stains, and text outside the template are detected by OCR software as unreadable noise. The software relies on binary decisions. A single deviating remark in the margin of a waybill—for example, a handwritten “2 pallets returned”—breaks the logic of text recognition. This results in hard extraction errors, where the engine fails to recognize the text, or enters incorrect characters into the enterprise software (WMS or TMS). When in doubt, the system kicks the document back into a queue for human validation.
The conflict between rigid templates and human behavior
OCR engines react to human interventions by getting stuck in their own template matching. When a worker at the dock writes an extra note straight across the order number field, the typed and handwritten inks merge. The software can no longer isolate the original coordinates. Customs stamps or driver signatures overlapping with printed barcodes reduce the reading rate to zero. The system halts the workflow because it can no longer guarantee the integrity of the data fields.
The hidden back-office bottleneck
Failing document recognition creates hours of additional burden for the back office. Every document that lands in the error log requires human attention. With peak season volumes, the manual review queue grows faster than it can be cleared. This generates a cumulative backlog.
As a result, specialized employees experience a shift in their duties. Customs declarants, logistics planners, and senior freight forwarders—professionals whose true value lies in problem-solving and coordination—are downgraded to manual data entry typists. They spend their workday opening scanned files on the left screen and manually retyping the unreadable data on the right screen. This dilutes the department’s operational brainpower exactly when it is needed most for scaling and continuity. Effectively tackling backlogs in CMR processing is essential to restore the operational flow.
Calculation example: The impact of a 15% failure rate on weekly planning
To illustrate the pressure on scheduling, consider a realistic calculation of fallout during the Christmas surge:
- Weekly starting volume: A logistics hub processes 5,300 documents per week in December (internal transfers, CMRs, and customs papers).
- Failure rate: Due to time pressure on the floor and suboptimal scans, the error rate rises to 15% of the incoming stream.
- Volume to the error queue: This results in 795 stalled documents per week.
- Recovery time per document: Opening the file, deciphering the handwritten note, typing it into the TMS, and saving the change takes an average of 3 minutes per document.
- Total hour burden: 795 documents x 3 minutes equals 2,385 minutes of unplanned work.
- Impact on planning: The department loses just under 40 hours a week to structural manual correction work, which is the exact equivalent of deploying one highly educated, full-time employee per week, solely focused on data cleaning.
Chain reaction: From unreadable document to compliance risk
Manually processing large volumes of exceptions creates new points of failure further down the process. Typing under high workload introduces human errors. As industry insights from parties like Klearstack confirm, typos in specific customs data have far-reaching consequences. A single number transposition in an HS tariff code, incorrectly copying the number of collies, or a faulty gross weight on a customs document escalates instantly.
Once incorrect data reaches national borders or port authorities, it results in hard compliance fines and detained shipments. Delays at EU checkpoints break SLAs with end customers. A fully automated system that skips quality controls and forcefully processes everything temporarily increases this risk. If the OCR reads an 8 as a 3, and the system accepts it without human validation, customs will halt the transport.
To bridge the gap between the unstructured paper reality at the dock and the required Data Accuracy in the system, the solution lies in a hybrid process flow. A setup where Robotic Process Automation (RPA) processes the standard documents, directly linked to external human oversight (BPO) for immediate scalability and quality assurance. This guarantees continuity without swallowing up local specialists with correction work.
The danger of typos under time pressure
Temporary administrative staff or stressed planners lack the built-in control mechanisms of dedicated software. A space in the wrong spot in a unique reference number means shipment status updates (milestones) will no longer match. This creates blind spots in the FMS or TMS. The customer loses sight of the shipment, the helpdesk is overloaded with status queries, and the operational unit loses control of the logistics process. For deeper insight into this process, explore how to maintain the accuracy of AI systems during logistics peaks.
Time pressure in peak seasons fractures the structure of incoming shipment data, directly leading to stalled OCR systems and back-office delays. Manual data entry by local staff to plug these gaps causes costly time loss and compliance risks through typos. DataMondial takes over this process as a specialized Dutch partner, combining RPA integrations with human oversight from our nearshoring Operations Center in Romania. Build operational resilience and protect your EU compliance through our hybrid document processing; contact us to outsource your data validation and processing scalably.