The Hidden Capacity Cost of Automation: Why Your AI Project Unexpectedly Requires Extra FTEs
The paradox of the automated back office
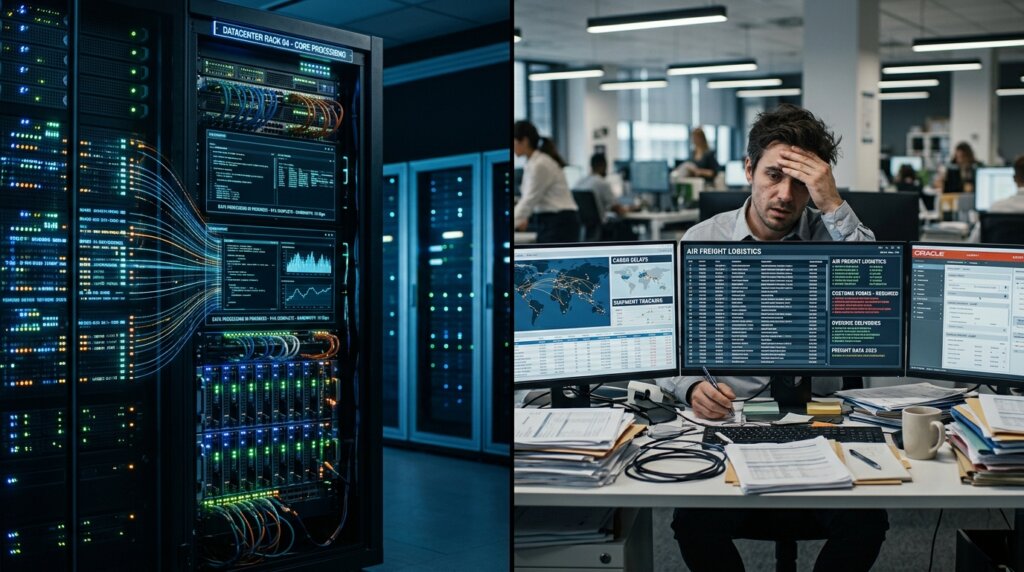
Automation promises reduced workloads and lower operational costs in the back office. However, post-implementation reality often paints a different picture. While the automated system processes the bulk of the data, it simultaneously generates a flood of complex edge cases. These exceptions demand immediate human intervention to keep the process from grinding to a halt. What was intended to structurally relieve your department instantly creates the need for additional FTEs just to monitor the AI’s output. Strategically resolving this capacity bottleneck through professional data validation for OCR, AI, and Machine Learning prevents stagnation in your daily operations.
The 80/20 trap with unstructured logistics data
Business processes that rely on unstructured logistics data typically hit a wall during the final twenty percent of the document flow. Algorithms and RPA systems thrive on standardized fields. If a document falls outside those digital parameters, the system simply refuses to process it. In practice, a Bill of Lading, packing slip, or customs certificate often contains irregular layouts, stamps overlapping text, or handwritten notes. When extracting container numbers, seal numbers, or specific proofs of delivery, the system immediately defaults to manual human validation.
Processing 100 standard documents through conventional manual data entry follows a predictable, constant rhythm. However, manually resolving 20 isolated AI exceptions shatters this rhythm, consuming a disproportionate amount of time and resources. Fully structured data streams, such as Electronic Data Interchange (EDI), avoid this bottleneck because the data points are predetermined. External, unstructured document flows, on the other hand, require a continuous, labor-intensive translation process.
The time paradox of an isolated error
An employee processing a standard document from start to finish builds context as they read. When assessing a single, isolated edge case flagged by an AI system, this context is entirely missing. The employee has to open the specific document, reverse-engineer the algorithm’s reasoning, locate the source of the error, and execute the correction. Because of this fragmented workflow, validating a single rejected field often takes more time than manually entering that entire document from scratch.
Specific documents versus structured EDI
Internal system standardization leads to frictionless processes. Structured EDI messages flow through internal systems without errors or human intervention. The real challenge arises with external document flows generated outside your sphere of influence. International supply chains produce a wide variety of freight and transport documentation, with every supplier or customs agent using their own unique formats. This inherent unpredictability makes the external data stream highly prone to errors when processed by systems built on rigid rules and strict pattern expectations.
Cognitive overload transforms your back office
The introduction of automation fundamentally changes the nature of work on the floor. As repetitive tasks disappear, employees are left to focus primarily on complex exceptions and problem-solving. This shift in responsibilities can place intense new pressures on your existing staff.
When systems take over the predictable tasks, what remains is a concentrated volume of cognitively demanding work. This can cause alertness and accuracy to decline, particularly when employees are forced to constantly evaluate edge cases.
Furthermore, there is a risk that employees will lose touch with the foundational basics of processes that have been heavily automated. A continuous stream of exception handling also drives up cognitive load, accelerating mental exhaustion. As a result, the quality of manual verification within a Human-in-the-Loop process can easily be compromised.
From routine to escalation management
Back-office employees are effectively transformed from data entry clerks into escalation managers. Their operational role is reduced to acting as a safety net for failing algorithms. Every notification on their screen represents an anomaly the system couldn’t process, forcing the employee to constantly switch gears between disparate error messages, software systems, and document types.
Mental exhaustion lowers data accuracy
A department that ceaselessly processes complex exceptions will inevitably lose its edge. While standard data entry involves moments of low cognitive load, resolving AI edge cases requires absolute, unrelenting focus. Paradoxically, this constant mental pressure allows more errors to slip through during human review, ultimately degrading your overall data accuracy.
Continuous model training demands senior subject matter experts
An AI implementation is not a finite project with a hard end date. The true operational investment begins after integration. Current research on LLMOps emphasizes that strategic capacity planning is crucial for maintaining high-quality output. Organizations consistently underestimate the hidden costs and man-hours required to guarantee long-term data accuracy.
Format drift and the need for retraining
Document formats in the logistics sector are in a constant state of flux. Shipping lines update their invoice terms, customs forms undergo revisions, and new trading partners introduce entirely unfamiliar layouts. Due to this “format drift,” the algorithm’s performance naturally degrades over time. Without manual human calibration, the RPA system will simply fail to recognize the modified fields. The necessary retraining can only be executed by experienced logistics professionals who deeply understand the subject matter. Consequently, this calibration pulls your senior staff away from their core activities and operational management duties.
Calculation example: the real costs per validation
The costs of exception handling quickly escalate when senior employees are tasked with making corrections within an RPA workflow.
Consider an automated process that generates 50 error notifications daily, each requiring manual RPA error correction:
Time investment: A senior subject matter expert spends an average of 4 minutes per error (reading the document, determining context, locating the error, and updating the system). This results in over 3.3 hours per day dedicated purely to exception handling.
Salary component: Assuming an internal rate of €45 per hour for a senior employee (including employer overhead), the direct cost amounts to €148.50 per workday.
Operational impact: On a monthly basis (22 working days), correcting this small, defined group of exceptions consumes 72 hours and costs €3,267.
This direct breakdown only accounts for the time spent processing. The lost revenue from pulling an expert away from strategic process optimization drives your true operational costs significantly higher.
Strategically outsource exception handling
Achieving a profitable ROI on your AI investment requires a strict separation between automated bulk processing and complex exception handling. Maintain the speed of your systems by choosing not to handle exceptions and the challenging validation of AI output internally. Instead, outsource this to a specialized team within the EU. As a Dutch BPO provider operating through nearshoring in Romania, DataMondial delivers the scalability, EU compliance, and specialized capacity necessary to scale your logistics AI pilot for production and eliminate operational bottlenecks. Relieve your internal organization and let our experts handle your data validation with continuous, uncompromising accuracy.